Web 爬虫下的 Python 数据分析:中情局全球概况图解 (#3520)
* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md

* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md

* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md

*  Web 爬虫下的 Python 数据分析:中情局全球概况图解

 Web 爬虫下的 Python 数据分析:中情局全球概况图解

* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md

* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md

* Update data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md
This commit is contained in:
 Starrier
+58
-58
@@ -2,58 +2,58 @@
|
||||
> * 原文作者:[Tirthajyoti Sarkar](https://towardsdatascience.com/@tirthajyoti?source=post_header_lockup)
|
||||
> * 译文出自:[掘金翻译计划](https://github.com/xitu/gold-miner)
|
||||
> * 本文永久链接:[https://github.com/xitu/gold-miner/blob/master/TODO/data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md](https://github.com/xitu/gold-miner/blob/master/TODO/data-analytics-with-python-by-web-scraping-illustration-with-cia-world-factbook.md)
|
||||
> * 译者:
|
||||
> * 校对者:
|
||||
> * 译者:[Starrier](https://github.com/Starriers)
|
||||
> * 校对者:[allenlongbaobao](https://github.com/allenlongbaobao)、[FateZeros](https://github.com/FateZeros)
|
||||
|
||||
# Data Analytics with Python by Web scraping: Illustration with CIA World Factbook
|
||||
# Web 爬虫下的 Python 数据分析:中情局全球概况图解
|
||||
|
||||
## In this article, we show how to use Python libraries and HTML parsing to extract useful information from a website and answer some important analytics questions afterwards.
|
||||
## 在本文章中,我将展示如何使用 Python 和 HTML 解析从网页中获取有价值的信息,之后会回答一些重要的数据分析问题。
|
||||
|
||||
|
||||
|
||||
In a data science project, almost always the most time consuming and messy part is the data gathering and cleaning. Everyone likes to build a cool deep neural network (or XGboost) model or two and show off one’s skills with cool 3D interactive plots. But the models need raw data to start with and they don’t come easy and clean.
|
||||
在数据科学项目中,数据采集和清洗几乎总是最耗时、最麻烦的步骤。每个人都喜欢用 3D 交互式图表来构建一两个很酷的深度神经网络(或者 XGboost)模型,以此炫耀个人的技术。但这些模型是需要原始数据的,而且它们并不容易采集和清洗。
|
||||
|
||||
> **Life, after all, is not Kaggle where a zip file full of data is waiting for you to be unpacked and modeled :-)**
|
||||
> **毕竟生活不像 Kaggle 一样是一个 zip 格式文件,等待您的解压和建模 :-)**
|
||||
|
||||
**But why gather data or build model anyway**? The fundamental motivation is to answer a business or scientific or social question. _Is there a trend_? _Is this thing related to that_? _Can the measurement of this entity predict the outcome for that phenomena_? It is because answering this question will validate a hypothesis you have as a scientist/practitioner of the field. You are just using data (as opposed to test tubes like a chemist or magnets like a physicist) to test your hypothesis and prove/disprove it scientifically. **That is the ‘science’ part of the data science. Nothing more, nothing less…**
|
||||
**但为什么我们要采集数据或者构建模型呢**?最初的动机是回答商业、科学或者是社会上的问题。**这是趋势么**?**事物间的关联性**?**实体的测量可以预测出这种现象的结果么**?因为回答这个问题将会验证您作为这个该领域的科学家/实践者所提出的假设。您只是在使用数据(而不是像化学家使用试管或者物理学家使用磁铁)来验证您的假设,并且科学地证明/反驳它。**这就是数据科学中的「科学」部分,名副其实……**
|
||||
|
||||
Trust me, it is not that hard to come up with a good quality question which requires a bit of application of data science techniques to answer. Each such question then becomes a small little project of your which you can code up and showcase on a open-source platform like Github to show to your friends. Even if you are not a data scientist by profession, nobody can stop you writing cool program to answer a good data question. That showcases you as a person who is comfortable around data and one who can tell a story with data.
|
||||
相信我,提出一个需要一些数据科学技术应用来解决的高质量问题并不难。而且每一个这样的问题都会成为您的一个小项目,您可以将它开源在 Gihub 这样的平台来和您的朋友们分享。即使您不是专业的数据专家,也没有人可以阻止您通过编写很酷的代码来回答一个高质量的数据问题。这也表明您是对数据敏感并且可以用数据讲故事的人。
|
||||
|
||||
Let’s tackle one such question today…
|
||||
今天让我们来解决这样一个问题。。。
|
||||
|
||||
> **Is there any relationship between the GDP (in terms of purchasing power parity) of a country and the percentage of its Internet users? And is this trend similar for low-income/middle-income/high-income countries?**
|
||||
> **一个国家的 GDP(按购买力平价)与其互联网用户比例是否有任何关系?这种趋势对于低收入/中等收入/高收入国家而言是否类似?**
|
||||
|
||||
Now, there can be any number of sources you can think of to gather data for answering this question. I found that an website from CIA (Yes, the ‘AGENCY’), which hosts basic factual information about all countries around the world, is a good place to scrape the data from.
|
||||
现在您可以想到许多原始资料可以采集来作为回答此问题的数据。我发现中情局(是的 ‘AGENCY’)的一个网站保存了世界上所有国家的基本事实信息,是一个采集数据的好地方。
|
||||
|
||||
So, we will use following Python modules to build our database and visualizations,
|
||||
因此我们将使用以下 Python 模块来构建我们的数据库和可视化,
|
||||
|
||||
* **Pandas**, **Numpy, matplotlib/seaborn**
|
||||
* Python **urllib** (for sending the HTTP requests)
|
||||
* **BeautifulSoup** (for HTML parsing)
|
||||
* **Regular expression module** (for finding the exact matching text to search for)
|
||||
* Python **urllib** (发送 HTTP 请求)
|
||||
* **BeautifulSoup** (用于 HTML 解析)
|
||||
* **Regular expression module** (用于查找要搜索的精确匹配文本)
|
||||
|
||||
Let’s talk about the program structure to answer this data science question. The [entire boiler plate code is available here](https://github.com/tirthajyoti/Web-Database-Analytics-Python/blob/master/CIA-Factbook-Analytics2.ipynb) in my [Github repository](https://github.com/tirthajyoti/Web-Database-Analytics-Python). Please feel free to fork and star if you like it.
|
||||
让我们讨论一下解决这个数据科学问题的程序结构。[整个项目代码](https://github.com/tirthajyoti/Web-Database-Analytics-Python/blob/master/CIA-Factbook-Analytics2.ipynb)在我的 [Github 仓库中都可以找到](https://github.com/tirthajyoti/Web-Database-Analytics-Python)。如果您喜欢的话,请 fork 或者给个 star。
|
||||
|
||||
#### Reading the front HTML page and passing on to BeautifulSoup
|
||||
#### 阅读 HTML 首页并传递给 BeautifulSoup
|
||||
|
||||
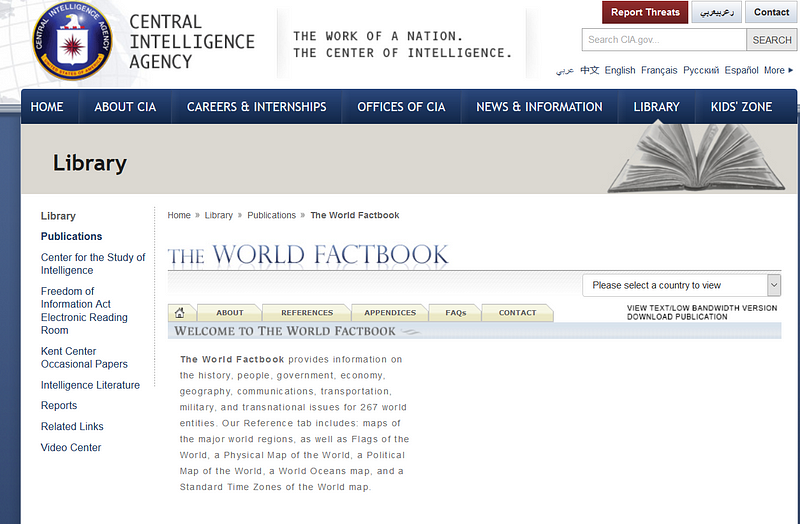
Here is how the [front page of the CIA World Factbook](https://www.cia.gov/library/publications/the-world-factbook/) looks like,
|
||||
这儿是[中情局全球概况首页](https://www.cia.gov/library/publications/the-world-factbook/)
|
||||
|
||||
|
||||
|
||||
Fig: CIA World Factbook front page.
|
||||
图:中情局全球概况首页
|
||||
|
||||
We use a simple urllib request with a SSL error ignore context to retrieve this page and then pass it on to the magical BeautifulSoup, which parses the HTML for us and produce a pretty text dump. For those, who are not familiar with the BeautifulSoup library, they can watch the following video or read this [great informative article on Medium](https://medium.freecodecamp.org/how-to-scrape-websites-with-python-and-beautifulsoup-5946935d93fe).
|
||||
我们使用一个带有 SSL 错误忽略上下文的简单 urllib 请求来检索这个页面,然后将它传递给神奇的 BeautifulSoup,它将为我们解析 HTML 并生成一个漂亮的文本转储。对于那些不熟悉 BeautifulSoup 库的人,他们可以观以下视频或者[在 Medium 上阅读这篇内容丰富的文章。](https://medium.freecodecamp.org/how-to-scrape-websites-with-python-and-beautifulsoup-5946935d93fe)
|
||||
|
||||
YouTube 视频地址:https://youtu.be/aIPqt-OdmS0
|
||||
|
||||
So, here is the code snippet for reading the front page HTML,
|
||||
以下是读取的首页 HTML 的代码片段,
|
||||
|
||||
```
|
||||
ctx = ssl.create_default_context()
|
||||
ctx.check_hostname = False
|
||||
ctx.verify_mode = ssl.CERT_NONE
|
||||
|
||||
# Read the HTML from the URL and pass on to BeautifulSoup
|
||||
# 从 URL 中读取 HTML 并将其传递给 BeautifulSoup
|
||||
url = 'https://www.cia.gov/library/publications/the-world-factbook/'
|
||||
print("Opening the file connection...")
|
||||
uh= urllib.request.urlopen(url, context=ctx)
|
||||
@@ -62,9 +62,9 @@ html =uh.read().decode()
|
||||
print(f"Reading done. Total {len(html)} characters read.")
|
||||
```
|
||||
|
||||
Here is how we pass it on to BeautifulSoup and use the `find_all` method to find all the country names and codes embedded in the HTML. Basically, the idea is to **find the HTML tags named ‘option’**. The text in that tag is the country name and the char 5 and 6 of the tag value represent the 2-character country code.
|
||||
以下是我们如何将其传递给 BeautifulSoup 并使用 `find_all` 方法查找 HTML 中嵌入的所有国家名称和代码。基本上,这个想法是**找到名为 ‘option’ 的 HTML 标签**。标签中的文本是国家名,标签值的 5 号和 6 号表示的是 2 个字符的国家代码。
|
||||
|
||||
Now, you may ask how would you know that you need to extract 5th and 6th character only? The simple answer is that **you have to examine the soup text i.e. parsed HTML text yourself and determine those indices**. There is no universal method to determine this. Each HTML page and the underlying structure is unique.
|
||||
现在您可能会问,您如何知道只需要提取第五和第六字符?简单的答案是**您必须亲自检查 soup 文本--即解析的 HTML 文本,并确定这些索引**。没有通用的方法来检查这一点,因为每个 HTML 页面和底层结构都是独一无二的。
|
||||
|
||||
```
|
||||
soup = BeautifulSoup(html, 'html.parser')
|
||||
@@ -79,25 +79,25 @@ temp=country_codes.pop(0) # To remove the first entry 'World'
|
||||
temp=country_names.pop(0) # To remove the first entry 'World'
|
||||
```
|
||||
|
||||
#### Crawling: Download all the text data of all countries into a dictionary by scraping each page individually
|
||||
#### 爬取:将所有国家的文本数据逐个抓取到字典中
|
||||
|
||||
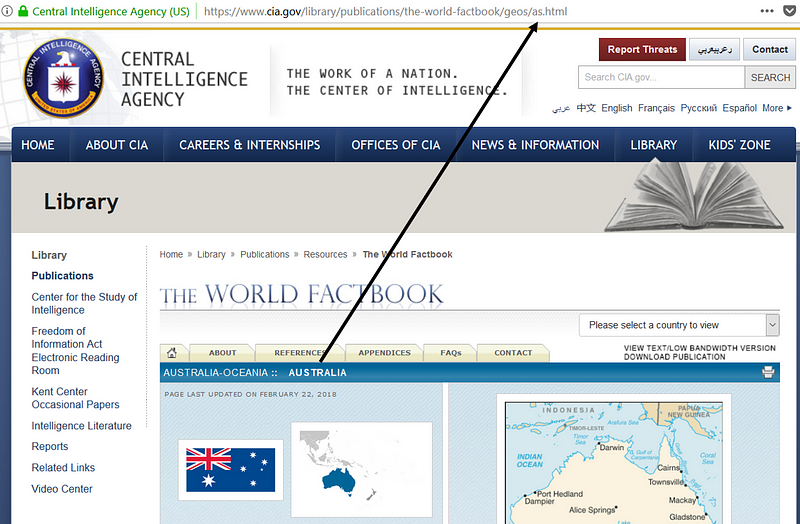
This step is the essential scraping or crawling as they say. To do this, **the key thing to identify is how the URL of each countries information page is structured**. Now, in general case, this is may be hard to get. In this particular case, quick examination shows a very simple and regular structure to follow. Here is the screenshot of Australia for example,
|
||||
这一步就是他们所说的爬取或者抓取。要实现这一点,**关键是要确定每个国家信息页面的 URL 是如何构造的**。现在的一般情况是,这将很难获得。特殊情况下,快速检查显示了一个非常简单并且有规律的结构,以澳大利亚截图为例。
|
||||
|
||||
|
||||
|
||||
That means there is a fixed URL to which you have to append the 2-character country code and you get to the URL of that country’s page. So, we can just iterate over the country codes’ list and use BeautifulSoup to extract all the text and store in our local dictionary. Here is the code snippet,
|
||||
这意味着有一个固定的URL,您必须附加两个字符的国家代码,并获得该国家的页面网址。因此,我们只需遍历国家代码列表,使用 BeautifulSoup 提取所有文本并存储在本地词典中。这是代码片,
|
||||
|
||||
```
|
||||
# Base URL
|
||||
# 基础 URL
|
||||
urlbase = 'https://www.cia.gov/library/publications/the-world-factbook/geos/'
|
||||
# Empty data dictionary
|
||||
# 空数据字典
|
||||
text_data=dict()
|
||||
|
||||
# Iterate over every country
|
||||
# 遍历每个国家
|
||||
for i in range(1,len(country_names)-1):
|
||||
country_html=country_codes[i]+'.html'
|
||||
url_to_get=urlbase+country_html
|
||||
# Read the HTML from the URL and pass on to BeautifulSoup
|
||||
# 从 URL 中读取 HTML 并将其传递给 BeautifulSoup
|
||||
html = urllib.request.urlopen(url_to_get, context=ctx).read()
|
||||
soup = BeautifulSoup(html, 'html.parser')
|
||||
txt=soup.get_text()
|
||||
@@ -107,30 +107,30 @@ for i in range(1,len(country_names)-1):
|
||||
print ("\n**Finished downloading all text data!**")
|
||||
```
|
||||
|
||||
#### Store in a Pickle dump if you like
|
||||
#### 如果您喜欢,可以存放在一个 Pickle dump 中
|
||||
|
||||
For good measure, I prefer to serialize and **store this data in a** [**Python pickle object**](https://pythontips.com/2013/08/02/what-is-pickle-in-python/)anyway. That way I can just read the data directly next time I open the Jupyter notebook without repeating the web crawling steps.
|
||||
另外,我偏向于序列化并**将数据存储在**[**Python pickle 对象中**](https://pythontips.com/2013/08/02/what-is-pickle-in-python/)。这样我下次打开 Jupyter 笔记本时,就可以直接读取数据而无需重复网络爬行步骤。
|
||||
|
||||
```
|
||||
import pickle
|
||||
pickle.dump(text_data,open("text_data_CIA_Factobook.p", "wb"))
|
||||
|
||||
# Unpickle and read the data from local storage next time
|
||||
# 取消选择,下次从本地存储区读取数据。
|
||||
text_data = pickle.load(open("text_data_CIA_Factobook.p", "rb"))
|
||||
```
|
||||
|
||||
#### Using regular expression to extract the GDP/capita data from the text dump
|
||||
#### 使用正则表达式从文本转储中提取 GDP/人均数据
|
||||
|
||||
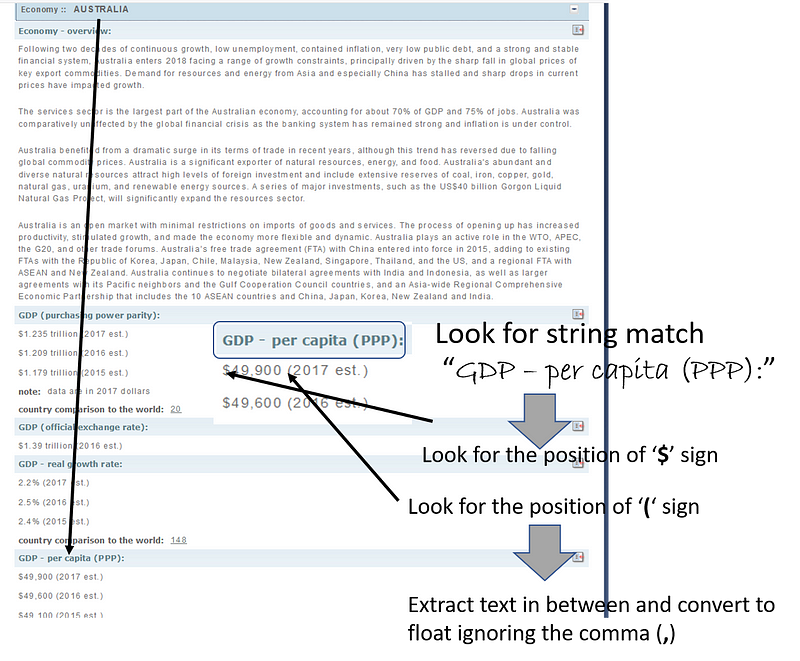
This is the core text analytics part of the program, where we take help of [**_regular expression_** module](https://docs.python.org/3/howto/regex.html) to find what we are looking for in the huge text string and extract the relevant numerical data. Now, regular expression is a rich resource in Python (or in virtually every high level programming language). It allows searching/matching particular pattern of strings within a large corpus of text. Here, we use very simple methods of regular expression for matching the exact words like “_GDP — per capita (PPP):_” and then read few characters after that, extract the positions of certain symbols like $ and parentheses to eventually extract the numerical value of GDP/capita. Here is the idea illustrated with a figure.
|
||||
这是程序的核心文本分析部分,我们借助[**正则表达式**模块](https://docs.python.org/3/howto/regex.html)来查找我们在庞大文本字符串中寻找的内容,并提取相关的数字数据。现在,正则表达式是 Python(或者几乎是所有的高级编程语言)中的一个丰富资源。它允许在大量文本中以特定模式搜索/匹配字符串。这里我们使用非常简单的正则表达式方法来匹配精确的单词,如“**GDP — per capita (PPP):**”然后读取几个字符,提取诸如 $ 和 () 等特定符号的位置,最后提取 GDP/人均数值。这是一个用数字说明的想法。
|
||||
|
||||
|
||||
|
||||
Fig: Illustration of the text analytics.
|
||||
图:文本分析图示。
|
||||
|
||||
There are other regular expression tricks used in this notebook, for example to extract the total GDP properly regardless whether the figure is given in billions or trillions.
|
||||
这个笔记本中还有其他一些常用的表达方式,例如,不管这个数字是以数十亿还是数万亿美元计算出来的,都可以正确地提取出 GDP 总量。
|
||||
|
||||
```
|
||||
# 'b' to catch 'billions', 't' to catch 'trillions'
|
||||
# 'b' 去捕捉 'billions', 't' 去捕捉 'trillions'
|
||||
start = re.search('\$',string)
|
||||
end = re.search('[b,t]',string)
|
||||
if (start!=None and end!=None):
|
||||
@@ -139,18 +139,18 @@ if (start!=None and end!=None):
|
||||
a=string[start+1:start+end-1]
|
||||
a = convert_float(a)
|
||||
if (string[end]=='t'):
|
||||
# If the GDP was in trillions, multiply it by 1000
|
||||
# 如果 GDP 数值在 万亿中,则乘以 1000
|
||||
a=1000*a
|
||||
```
|
||||
|
||||
Here is the example code snippet. **Notice the multiple error-handling checks placed in the code**. This is necessary because of the supremely unpredictable nature of HTML pages. Not all country may have the GDP data, not all pages may have the exact same wordings for the data, not all numbers may look same, not all strings may have $ and () placed similarly. Any number of things can go wrong.
|
||||
以下是代码片段的示例。**注意放置在代码中的多个错误处理检查**。这是必要的,因为 HTML 页面具有极不可预测性。并非所有国家都有 GDP 数据,并非所有页面的数据措辞都完全相同,并非所有数字看起来都一样,并非所有字符串放置方式都类似于 $ 和 ()。任何事都可能出错。
|
||||
|
||||
> It is almost impossible to plan and write code for all scenarios but at least you have to have code to handle the exception if they occur so that your program does not come to a halt and can gracefully move on to the next page for processing.
|
||||
> 为所有的场景规划和编写代码几乎是不可能,但至少要有代码来处理可能出现的异常,这样您的程序才不会停止,并且可以继续优雅地进行下一页处理。
|
||||
|
||||
```
|
||||
# Initialize dictionary for holding the data
|
||||
# 初始化保存数据的字典
|
||||
GDP_PPP = {}
|
||||
# Iterate over every country
|
||||
# 遍历每个国家
|
||||
for i in range(1,len(country_names)-1):
|
||||
country= country_names[i]
|
||||
txt=text_data[country]
|
||||
@@ -168,7 +168,7 @@ for i in range(1,len(country_names)-1):
|
||||
a = convert_float(a)
|
||||
if (a!=-1.0): #If the float conversion fails somehow
|
||||
print(f"GDP/capita (PPP) of {country}: {a} dollars")
|
||||
# Insert the data in the dictionary
|
||||
# 在字典中插入数据
|
||||
GDP_PPP[country]=a
|
||||
else:
|
||||
print("**Could not find GDP/capita data!**")
|
||||
@@ -179,21 +179,21 @@ for i in range(1,len(country_names)-1):
|
||||
print ("\nFinished finding all GDP/capita data")
|
||||
```
|
||||
|
||||
#### Don’t forget to use pandas inner/left join method
|
||||
#### 不要忘记使用 pandas inner/left join 方法
|
||||
|
||||
One thing to remember is that all these text analytics will produce dataframes with slightly different set of countries as different types of data may be unavailable for different countries. One could use a [**Pandas left join**](https://pandas.pydata.org/pandas-docs/stable/merging.html) to create a dataframe with intersection of all common countries for which all the pieces of data is available/could be extracted.
|
||||
需要记住的一点是,所有这些分本分析都将产生具有略微不同的国家集的数据。因为不同的国家可能无法获得不同类型的数据。人们可以使用一个 [**Pandas left join**](https://pandas.pydata.org/pandas-docs/stable/merging.html) 来创建一个与所有可获得/可以提取的所有数据片段的所有公共国家相交的数据。
|
||||
|
||||
```
|
||||
df_combined = df_demo.join(df_GDP, how='left')
|
||||
df_combined.dropna(inplace=True)
|
||||
```
|
||||
|
||||
#### Ah the cool stuff now, Modeling…but wait! Let’s do filtering first!
|
||||
#### 啊,现在是很酷的东西,建模。。。但等等!还是先过滤吧!
|
||||
|
||||
After all the hard work of HTML parsing, page crawling, and text mining, now you are ready to reap the benefits — eager to run the regression algorithms and cool visualization scripts! But wait, often you need to clean up your data (particularly for this kind of socio-economic problems) a wee bit more before generating those plots. Basically, you want to filter out the outliers e.g. very small countries (like island nations) who may have extremely skewed values of the parameters you want to plot but does not follow the main underlying dynamics you want to investigate. A few lines of code is good for those filters. There may be more _Pythonic_ way to implement them but I tried to keep it extremely simple and easy to follow. The following code, for example, creates filters to keep out small countries with < 50 billion of total GDP and low and high income boundaries of $5,000 and $25,000 respectively (GDP/capita).
|
||||
在完成了所有的 HTML 解析、页面爬取和文本挖掘后,现在您已经可以享受这些好处了--渴望运行回归算法和很酷的可视化脚本!但是等等,在生成这些东西之前,通常您需要清洗您的数据(特别是针对这种社会经济问题)。基本上,您需要过滤掉异常值,例如非常小的国家(比如岛屿国家),它们可能对您要绘制的参数值造成极大的偏差,且不遵循您想要研究的主要基本动态。对这些过滤器来说,几行代码是很好的。可能有更多的 **Pythonic** 方法来实现他们,但我尽量保持它极其简单且易于遵循。例如,下面的代码创建过滤器,将 GDP 小于五百亿的小国拒之门外,低收入和高收入的界限分别为 5000 美元和 25000 美元(GDP/人均 GDP)。
|
||||
|
||||
```
|
||||
# Create a filtered data frame and x and y arrays
|
||||
# 创建过滤后的数据帧、x 和 y 数组
|
||||
filter_gdp = df_combined['Total GDP (PPP)'] > 50
|
||||
filter_low_income=df_combined['GDP (PPP)']>5000
|
||||
filter_high_income=df_combined['GDP (PPP)']<25000
|
||||
@@ -201,25 +201,25 @@ filter_high_income=df_combined['GDP (PPP)']<25000
|
||||
df_filtered = df_combined[filter_gdp][filter_low_income][filter_high_income]
|
||||
```
|
||||
|
||||
#### Finally, the visualization
|
||||
#### 最后是可视化
|
||||
|
||||
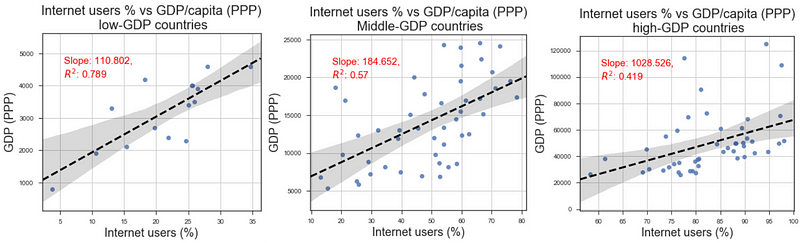
We use [**seaborn regplot** function](https://seaborn.pydata.org/generated/seaborn.regplot.html) to create the scatter plots (Internet users % vs. GDP/capita) with linear regression fit and 95% confidence interval bands shown. They look like following. One can interpret the result as
|
||||
我们使用 [**seaborn regplot** 函数](https://seaborn.pydata.org/generated/seaborn.regplot.html)创建线性回归拟合的散点图(互联网用户数量比上人均 GDP)和显示 95% 置信区间带。他们看起来就像下面一样。可以将结果解释为
|
||||
|
||||
> There is a strong positive correlation between Internet users % and GDP/capita for a country. Moreover, the strength of correlation is significantly higher for low-income/low-GDP countries than the high-GDP, advanced nations. **That could mean access to internet helps the lower income countries to grow faster and improve the average condition of their citizens more than it does for the advanced nations**.
|
||||
> 一个国家的互联网用户数量与人均 GDP 之间存在着很强的正相关关系。此外,低收入/低 GDP 国家的相关强度明显高于高 GDP 发达国家。**这可能意味着,与发达国家相比,互联网接入有助于低收入国家更快地增长,并更好地改善其公民的平均状况**。
|
||||
|
||||
|
||||
|
||||
#### Summary
|
||||
#### 总结
|
||||
|
||||
This article goes over a demo Python notebook to illustrate how to crawl webpages for downloading raw information by HTML parsing using BeautifulSoup. Thereafter, it also illustrates the use of Regular Expression module to search and extract important pieces of information what the user demands.
|
||||
本文通过一个 Python 笔记本演示来说明如何通过使用 BeautifulSoup 进行 HTML 解析来抓取用于下载原始信息的网页。在此基础上,阐述了如何利用正则表达式模块来搜索和提取用户所需要的重要信息。
|
||||
|
||||
> Above all, it demonstrates how or why there can be no simple, universal rule or program structure while mining messy HTML parsed texts. One has to examine the text structure and put in place appropriate error-handling checks to gracefully handle all the situations to maintain the flow of the program (and not crash) even if it cannot extract data for all those scenarios.
|
||||
> 最重要的是,它演示了在挖掘杂乱的HTML解析文本时,如何或为什么不可能有简单、通用的规则或程序结构。我们必须检查文本结构,并设置适当的错误处理检查,以便恰当地处理所有情况,以维护程序的流程(而不是崩溃),即使它无法提取所有这些场景的数据。
|
||||
|
||||
I hope readers can benefit from the provided Notebook file and build upon it as per their own requirement and imagination. For more web data analytics notebooks, [**please see my repository.**](https://github.com/tirthajyoti/Web-Database-Analytics-Python)
|
||||
我希望读者能从提供的笔记本文件中获益,并根据自己的需求和想象力在此基础上构建。更多 Web 数据分析笔记 [**请查看我的仓库**](https://github.com/tirthajyoti/Web-Database-Analytics-Python)
|
||||
|
||||
* * *
|
||||
|
||||
If you have any questions or ideas to share, please contact the author at [**tirthajyoti[AT]gmail.com**](mailto:tirthajyoti@gmail.com). Also you can check author’s [**GitHub repositories**](https://github.com/tirthajyoti?tab=repositories) for other fun code snippets in Python, R, or MATLAB and machine learning resources. If you are, like me, passionate about machine learning/data science, please feel free to [add me on LinkedIn](https://www.linkedin.com/in/tirthajyoti-sarkar-2127aa7/) or [follow me on Twitter.](https://twitter.com/tirthajyotiS)
|
||||
如果您有任何问题和想法可以分享,请联系作者 [**tirthajyoti@gmail.com**](mailto:tirthajyoti@gmail.com)。当然您也可以查看作者的 [**GitHub 仓库**](https://github.com/tirthajyoti?tab=repositories)中的 Python, R, 或者 MATLAB 和机器学习的资源。如果你像我一样热衷于机器学习/数据科学,请随时在[ LinkedIn 上添加我](https://www.linkedin.com/in/tirthajyoti-sarkar-2127aa7/)或者[在 Twitter 上关注我。](https://twitter.com/tirthajyotiS)
|
||||
|
||||
|
||||
---
|
||||
|
||||
Reference in New Issue
Block a user